Python 3.15, the next stable version of Python, is available now, along with new versions of Ruff, uv, and ty!
To get started, update uv, upgrade to Python 3.15, and install the latest versions of Ruff and ty:
uv self update
uv python upgrade 3.15
uv tool install ruff@latest
uv tool install ty@latest
Python 3.15 includes many exciting new features. We've chosen some of our favorites to describe below, along with related changes in our tools.
Lazy imports #
Python 3.15 introduces a new lazy keyword that can be used to defer loading of imports, avoiding
the cost of importing modules until they are actually needed. In many cases, lazy imports can
replace both function-local and TYPE_CHECKING imports that were used to defer expensive imports,
allowing you to keep more imports in one block at the top of a file, as recommended by PEP 8. As
long as the imports aren't actually used at runtime, they won't be loaded immediately.
You can get a taste for how lazy imports work with a brief REPL session. Regular imports immediately
install their modules in sys.modules, while lazy imports instead appear only in sys.lazy_modules
until their first runtime usage.1 Note that the annotation for x does not count as a runtime
usage because of the deferred annotation semantics introduced in Python 3.14.
>>> import sys
>>> import json
>>> 'json' in sys.modules
True
>>> lazy import tomllib
>>> # Accessing `tomllib` in an annotation does not load the module
>>> x: tomllib.TOMLDecodeError
>>> 'tomllib' in sys.modules
False
>>> 'tomllib' in sys.lazy_modules
True
>>> # Using `tomllib` at runtime finally loads the module
>>> tomllib.loads("tool.ruff.target-version = 'py315'")
{'tool': {'ruff': {'target-version': 'py315'}}}
>>> 'tomllib' in sys.modules
True
Ruff v0.17 stabilizes two new rules to help you manage your lazy imports and updates existing rules
to respect import laziness. First, lazy-import-mismatch (TID254) allows you to
configure lists of imports that should always be lazy or never be lazy and enforce this in your
project. For example, with the following configuration:
[lint.flake8-tidy-imports]
ban-lazy = ["json"]
require-lazy = ["typing"]
TID254 would be emitted on both of these imports:
lazy from json import loads  # TID254: `json` should be imported eagerly
import typing  # TID254: `typing` should be imported lazily
Both diagnostics come with an autofix to apply the correct laziness. For convenience, ban-lazy
and require-lazy also recognize a special all selector. See their documentation for more
details.
Second, lazy-import-immediately-resolved (TID255) helps to identify cases where a
nominally lazy import is actually loaded eagerly, defeating the purpose of marking it lazy. For
example, using foo.Bar as a base class causes the foo module to be loaded:
lazy import foo

class C(foo.Bar): ...
It would typically require substantial restructuring to avoid using such an import eagerly, so the
rule offers a fix to remove lazy from the import to make its immediate use clearer.
For projects that support older Python versions in addition to 3.15, PEP 810 also introduced the
__lazy_modules__ global variable. A definition like the following:
__lazy_modules__ = ["typing"]

import typing
has the same effect as lazy import typing but without using new syntax that would be rejected by
older Python versions. Ruff recognizes both forms as well.
In addition to these new rules, typing-only-first-party-import (TC001),
typing-only-third-party-import (TC002), and typing-only-standard-library-import
(TC003) have also been updated both to recognize lazy imports as an alternative to
TYPE_CHECKING blocks and to recommend using them on Python 3.15 and later.
On the uv side, we've added a preview feature that
allows making all build backend imports lazy, speeding up wheel builds by as much as 18% in our
benchmarks. Build backends are used to transform source code into a source distribution or wheel for
installing or sharing Python packages. This typically involves executing multiple short-lived Python
processes, where the overhead of unused runtime imports can be especially noticeable. You can try
the new preview feature with uv build --preview-features build-lazy-imports, which will make all
imports in the build backend lazy, without modifying its source code.2
New profiling tools in the standard library #
The new profiling module includes both a deterministic function-call tracing profiler in
profiling.tracing (relocated from cProfile) and a brand-new statistical profiler called Tachyon
in profiling.sampling. As a statistical profiler and unlike cProfile, Tachyon has "virtually
zero overhead" even at sampling rates up to one million samples per second. Further,
Tachyon can attach to running applications without any code modifications, making it ideal for
debugging performance issues, even in a live system.
In lieu of such a live system, the example below uses the RDKit library to count the number of atoms of each element in the first 5,000 molecules from its included sample of the National Cancer Institute dataset:
# element_counts.py

from collections import Counter
from pathlib import Path
from rdkit import Chem, RDConfig

def count_elements(symbols):
    return Counter(sum(symbols, []))

path = Path(RDConfig.RDDataDir) / "NCI/first_5K.smi"
molecules = Chem.SmilesMolSupplier(str(path), delimiter="\t", titleLine=False)
symbols = [
    [atom.GetSymbol() for atom in molecule.GetAtoms()]
    for molecule in molecules if molecule is not None
]
print(count_elements(symbols))
Tachyon can be invoked with uv, including the rdkit dependency:
uv run --python=3.15 --with rdkit==2026.3.6 \
  -m profiling.sampling run --flamegraph --browser \
  element_counts.py
which opens a nice HTML report with a flame graph in your browser:
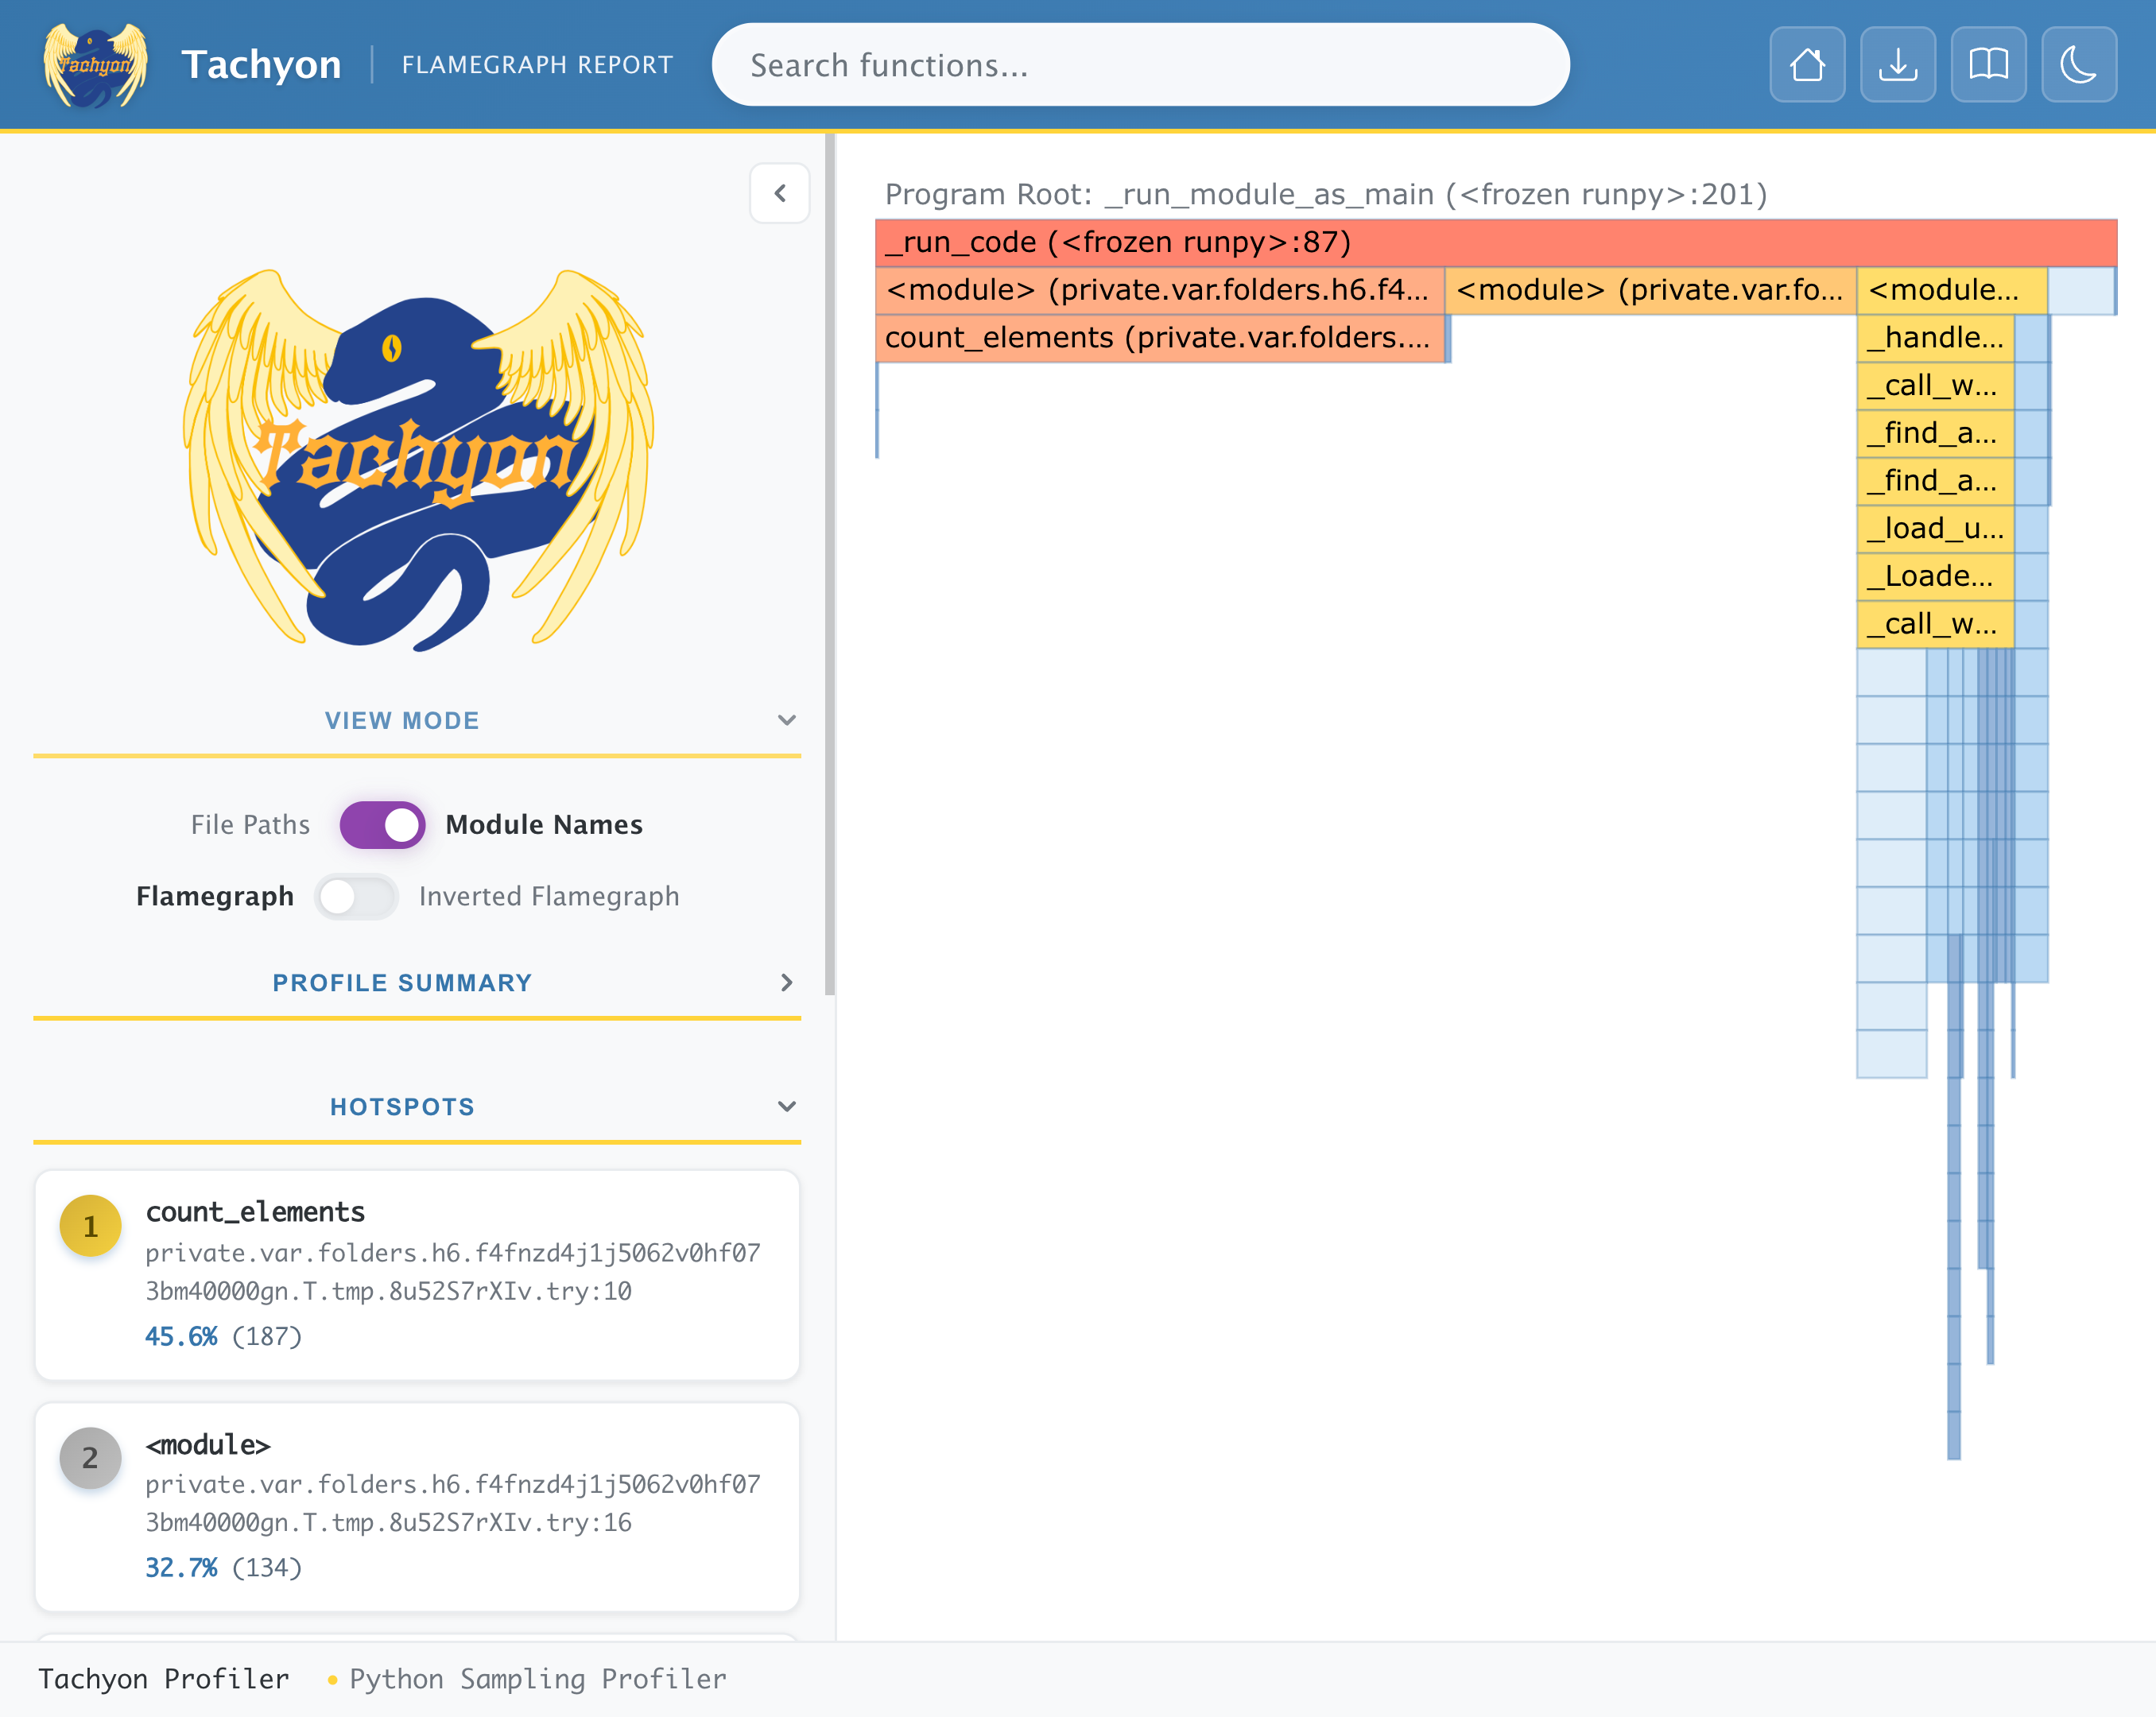
Using either the central flame graph or the hotspots section at the left, we can see that our
count_elements function accounts for 45.6% of samples. Fortunately, Ruff identifies a performance
improvement we can try, using the new
comprehension unpacking syntax, via quadratic-list-summation
(RUF017):
 def count_elements(symbols):
-    return Counter(sum(symbols, []))
+    return Counter([*sublist for sublist in symbols])
With this fix applied, the script runs in roughly half the time, dropping from ~0.45 seconds to ~0.22 seconds in a quick local benchmark.
New typing features #
Python 3.15 also includes a handful of new typing features. While these are only available in the
standard library typing module on 3.15 and later, the typing-extensions package makes them
available on earlier versions too. Both Ruff and ty treat the versions from typing-extensions
equivalently to those from typing.
closed and extra_items for typing.TypedDict #
PEP 728 introduced two new keyword arguments for typing.TypedDicts: the boolean closed
argument and extra_items, which allows specifying the type for any additional entries in the
TypedDict.
TypedDicts, as the name suggests, are variants of dicts that associate keys with corresponding
value types for their entries. Before Python 3.15, TypedDicts were always "open," meaning that
they could include keys beyond those in their definitions.
The code in the following example defines a Point2D type with two required fields, x and y.
Type-checkers like ty enforce that the right keys are provided in constructors, but because a
Point2D subtype could also include additional fields, iteration over the values of the dictionary
reveals a type of object instead of int.
from typing import TypedDict, reveal_type

class Point2D(TypedDict):
    x: int
    y: int

def f(point: Point2D):
    for value in point.values():
        reveal_type(value)  # Revealed type: `object`
Often, this is not desirable. By defining your TypedDict with closed=True instead, you can let
the type checker know that dictionaries of type Point2D will never contain additional fields.
After doing so, the revealed value type above changes to int, as you might
expect.
Along similar lines, the extra_items keyword argument specifies a single type for fields that
aren't explicitly listed in the TypedDict's definition. For example, we could make Point2D into
a more general Point class that allows any number of additional int dimensions, while preserving
the same values inference shown above:
class Point(TypedDict, extra_items=int): ...

def f(point: Point):
    for value in point.values():
        reveal_type(value)  # Revealed type: `int`
As demonstrated in these examples, ty understands these new keyword arguments, and Ruff does too.
typing.TypeForm #
PEP 747 introduced typing.TypeForm, which is a type for type annotations. That might sound a bit
arcane if you're not writing many functions that operate on types rather than values, but this is
useful for annotating such functions. To use an example from the PEP, consider a trycast function,
which attempts to cast a value to some type, returning None if this fails:
from typing import TypeForm

def trycast[T](typx: TypeForm[T], value: object) -> T | None: ...

trycast(str | None, 'hi')
Note that the typx argument is a type form, in this case a union of str and None. As with the
new TypedDict arguments above, both Ruff and ty have been updated to recognize TypeForm and
analyze its use accordingly.
New builtin types #
PEP 661 introduced a new sentinel type to the standard library, which can be used as a more
direct implementation of the common idiom of using object() as a sentinel value. Such sentinels
are often used as function defaults, where None is a useful value to distinguish from providing no
value at all. One downside of the old approach is that object() produces a rather opaque
description when printed:
>>> _sentinel = object()
>>> def f(value=_sentinel): ...
>>> help(f)
Help on function f in module __main__:

f(value=<object object at 0x1089e0830>)
Instead, the new sentinel builtin requires a string argument, which specifies the name of the
resulting sentinel object. Repeating our example with sentinel shows the improved output:
>>> MISSING = sentinel("MISSING")
>>> def f(value=MISSING): ...
>>> help(f)
Help on function f in module __main__:

f(value=MISSING)
As the PEP notes, this has other benefits beyond signature help. object() sentinels can also
misbehave when being copied or pickled as is comparisons will then return False. The new
sentinel handles these cases properly too.
Python 3.15 also includes the new frozendict type introduced in PEP 814. frozendict is an
immutable dict type, much like the analogous set variant, frozenset, which was added way back in
Python 2.4, when set itself was first introduced. PEP 814 wasn't the first time frozendict
was suggested either, with the previous PEP 416 eventually being rejected without enough
compelling use cases. As PEP 814 points out, the intervening fourteen years have provided such
compelling uses, including the addition of asyncio in Python 3.4 and, more recently, the additions
of free-threading in Python 3.13 and concurrent.interpreters in Python 3.14. These new ways of
easily accessing data concurrently make immutable data structures more important than ever.
Ruff's knowledge of the standard library has been upgraded to include both of these types, as well
as the PEP-585-style generic frozendicts, such as frozendict[str, int].
Unpacking in comprehensions #
PEP 798 expanded the use of * and ** to allow unpacking of comprehension elements:
>>> [*x for x in [[1, 2, 3], [4, 5, 6]]]
[1, 2, 3, 4, 5, 6]
>>> {**x for x in [{1: 2}, {3: 4}]}
{1: 2, 3: 4}
This is a further generalization of the unpacking introduced in PEP 448, which allowed using *
and ** in collection literals. As noted in PEP 798, the new syntax is a more concise alternative
to standard-library APIs like itertools.chain and functools.reduce. In line with this,
quadratic-list-summation (RUF017) now recommends the use of the new syntax on Python
3.15 and later, instead of functools.reduce and operator.iadd.
A performance boost for Windows users #
Last year we described a performance boost for Python interpreters built with Clang 19 and later,
which we used for our Python distribution shipped with uv, python-build-standalone. This change
has now been incorporated into upstream and python-build-standalone Windows x86-64 builds as well,
bringing as much as 15-20% performance improvements on the pyperformance
benchmark suite, even higher than the 3-5% seen for Linux and macOS platforms.
ARM64 Windows builds #
Windows ARM64 builds of CPython are becoming the default for Windows ARM64 users in both the
upstream Python install manager and in uv. Even on ARM64 platforms, x86-64 Python builds were
previously the default because released wheels were more common for this architecture and could
still be run on ARM systems via emulation. As described in last year's DPO thread, ARM64 has
become much more widely supported, to the point that it can be made the default. This also coincides
with the promotion of the aarch64-pc-windows-msvc target from Tier 3 to Tier 2, where issues with
builds must be fixed more quickly and block new releases.
Note that this affects more than just Python 3.15. All versions of Python on ARM64 Windows will now
default to ARM64 builds, where available. If you need to revert to the x86-64 builds for whatever
reason, you can use the UV_PYTHON_ARCH=x86_64 environment variable or explicitly request a
specific architecture as part of your Python version, as in
uv python install cpython-3.15-windows-x86_64.
Python 3.10 is reaching end of life #
Python 3.10 was first released in October 2021, and is reaching the end of its five-year support
window. As a result, Ruff v0.17 increases the default Python version from 3.10 to 3.11. This default
value only applies if you don't have a more specific target-version selected in your Ruff
configuration or requires-python in your pyproject.toml. Similarly, this change doesn't affect
Ruff's minimum supported Python version, which remains Python 3.7. uv will also continue to support
Python 3.10, but no new builds will be published after its final release, in line with the end of
upstream security support.
Support for ruff-lsp has been removed #
Ruff v0.17 removes support for ruff-lsp, our Python-based language server that was deprecated in
Ruff v0.9.5. The Ruff VS Code extension now always uses the native language server, and
the ruff.nativeServer setting is deprecated and ignored. If you’re still using ruff-lsp or legacy
settings such as ruff.lint.args or ruff.format.args, see the migration guide. If something
prevents you from switching to the native server, please open an issue to help us understand your
use case and what’s blocking your migration.
What else is changing? #
If you want to know more, you can find an extensive list of the changes to Python in the "What's new in Python 3.15" page. You can also check out the full changelogs for Ruff, uv, and ty on GitHub.
Read more about Astral — the company behind these tools.
Thanks to Dhruv Manilawala, David Peter, Micha Reiser, and Alex Waygood who contributed to this blog post.
Footnotes #
-
As I found out while writing this, the REPL's tab-completion can force imports to be resolved! So be sure to type out the example in full, if you're following along. ↩
-
uv uses CPython's new
-X lazy_imports=allflag to do this. You can try this, or thePYTHON_LAZY_IMPORTS=allenvironment variable, on your own code as well. ↩